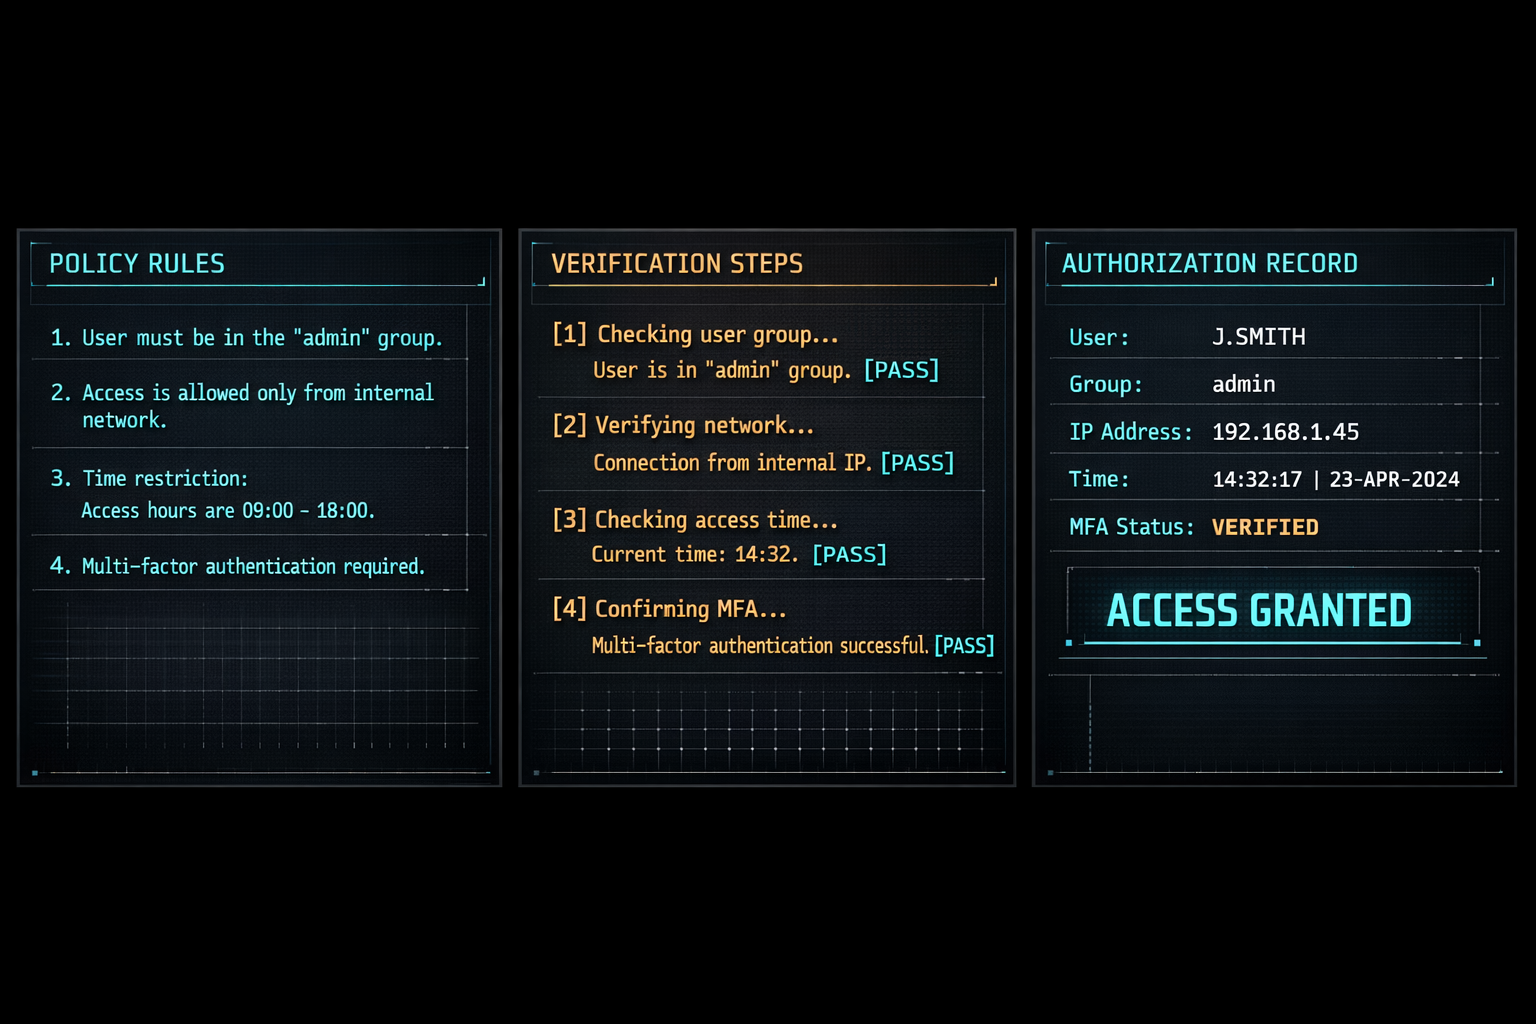
The rule set, the model's clause-by-clause reasoning, and the action it authorised, stored as one replayable record
The primitive, in one paragraph
Auditable reasoning is not a model that explains itself. It is a system of record in which four things are the same inspectable object: the exact rules a model was placed under, the model's stated reasoning bound step-by-step to those rules, the evidence it used and — just as loudly — the evidence it was never given, and the verdict with what would change it. Preserve that object for every consequential call, run several independent models against the same pinned rules, refuse to act when their derivations diverge, and you have converted "AI governance" from policy documents surrounding a model into the model's own inspectable operating procedure.
This page states the mechanism exactly, shows one real governed finding, and links the worked cases: a statute, a contract dispute, a medical coverage claim, an image-bearing record.
The one sequence to understand
Three independent models, each called fresh with no memory, receive the identical governing prompt and the identical record. All three reach the same verdict. Their controlling clauses differ. The gate refuses to authorise — and you can open every raw payload and check exactly why each model got there. That sequence is the whole thing. It is not a consensus panel (those count votes), not an observability trace (those log calls), not a compliance dashboard (those assert coverage). It is a governed decision you can take apart at any joint. Both worked cases below end on exactly that refusal.
What an ordinary agent trace shows, and what this shows
A typical published trace is: prompt → tool calls → output. Useful for debugging, useless for accountability, because the questions that matter are unanswerable from it: which rule authorized this? what evidence supported it? what did the model never see? why not the other action? was the claimed outcome verified?
A governed record here answers each one as a field:
controlling clauses → known facts (each with its source record) → unknown facts (and what
they would change) → proposed action → rejected alternative (named, with why) → expected
result → failure response → records absent → verification required → verdict → what would
flip it
The difference is not verbosity. It is formal correspondence between governing rules, stated reasoning, and machine action — one object a reader can interrogate at any joint.
The constitution
The rules are not a paragraph of encouragement. Every consequential call runs under the Decision Constitution (decision-constitution@1.1.0), a versioned object the live system returns verbatim:
curl -s -X POST https://miscsubjects.com/api/dispatch \
  -H 'content-type: application/json' \
-d '{"key":"DECISION_CONSTITUTION","body":""}'Its clauses, compressed: the rules given are law for this call and refusal is a recorded right (C2); stop on uncertainty rather than answer fluently (C3); no decoration, assume the reader is harmed by anything inexact (C4); every output is an isolated logical proof (C5); a seven-step numbered reasoning protocol in which every step names its controlling clause (C6); a mandatory list of the records a competent reviewer would have expected that were NOT supplied (C7); a structured decision record ending in a verdict (C8); nothing is called done without the record proving it (C9); no repeated failing retries (C10); a genuine rule conflict is named, never silently resolved (C11).
The constitution travels inside the request payload. The preserved object therefore carries the exact law its model was under — the version, not a paraphrase — which is what makes a year-later audit possible without trusting anyone's memory.
Lineage: the reasoning columns became the ledger
This is not a fresh idea dressed in new machinery. It is the oldest idea in this system.
In the owner's original build — June 2026, running on a spreadsheet — every model turn was governed by numbered clause law (A1, the master law; A2, the reasoning protocol). The model was required to emit a numbered REASONING block before any reply or tool call: which clauses apply, what is known, what is unknown, what it is about to do, why not the alternative, what it expects, what it will do if wrong — ending in a DECISION line. The runtime then stripped that block from the user's reply and wrote three columns on every loop: the raw model output, the raw tool call, the tool result.
Three audit columns in a spreadsheet. That was the ledger, before the ledger. The protocol required verification before any confirmation — a write was not "done" until a read-back proved it — and clause insertion into the law itself went through a tool that preserved everything already there. The original protocol is preserved verbatim, contacts scrubbed, as a guidebook in this repository: prompts/original-decision-protocol-2026-06.md.
What the present system adds is generality and adversarial depth: hash-pinned rule sets, complete gateway payloads instead of output columns, several model families instead of one, a deterministic seal instead of a single verdict, receipts a stranger can open instead of columns an owner can read. The primitive did not change. Its proof surface did.
One real governed finding
Below is a complete finding from the contract case — the anatomy above, produced by a live model under the constitution, verbatim including its imperfections:
Note the parts an ordinary trace never contains: the model recites the conditions it operates under and the hashes that pin them; it lists what it was not given — the signed agreement, the claim email's provable transmission date, any waiver — before reasoning at all; each step names its clause; the strongest alternative (the customer deserves the credit because the outage was real) is named and rejected on clause grounds; and the finding states what would flip it.
The gate, and why unanimity is not enough
Both new cases ended the same instructive way: three model families, three DENY verdicts — and the deterministic seal returned ESCALATE, not APPROVE.
The refusal has two grounds. Caller-supplied findings run in a mode that can never authorise — only records the sealer loads itself can. And the clause citations diverged across seats: same conclusion, different derivations. The gate treats that as unresolved because it is: two reasoners who agree for different stated reasons have not checked each other, they have coincided. Majority voting cannot see this. Derivation-level comparison can, and it is only possible because the constitution forces every finding into a shape where derivations are comparable.
The same chain, four evidence burdens
| case | rules | artifact | panel | outcome |
|---|---|---|---|---|
| EU AI Act, Article 50 | statute, verbatim, pinned | a deployed system's description | five seats | receipted adjudication; the probe report measures each seat's error rate |
| contract service credit | six agreement clauses, hashed | monitoring export + late claim, synthetic and labeled | three families | unanimous DENY, sealed ESCALATE on derivation divergence |
| medical prior authorization | payer policy, hashed, with its own not-clinical-judgment clause | submitted clinical note, synthetic and labeled | three families | unanimous DENY, each seat naming the record that would flip it, sealed ESCALATE |
| image-bearing record | pinned rule set | hashed synthetic radiograph + record | four seats + recorded adversary | the silent pixel loss and the false-confidence event, preserved |
One machinery. What changes per case is the evidence burden, the consequence of being wrong, and therefore — under logical economics — how much reasoning the question is worth and how tight the error bound must be before anything acts.
The honest limits
The constitution constrains stated reasoning, not hidden computation — the defensible object is the model's stated decision rationale plus its complete execution trace, and this page claims nothing about chain-of-thought faithfulness. Findings differ in format across families, so clause extraction has edge cases, visible in the case pages. The fixtures in the two new cases are synthetic and say so inside the artifact. And no bound assembly has ever reached APPROVE — the gate's sensitivity is proven; its acceptance path is not yet exercised by a real panel. Every one of these belongs to a reader before it belongs to a defense.
PARTIAL 4/6 This page is a proof object. Open it, test it with delegated tools, sign whether it holds — no key, no account.
What is checked
- published and rendered The page is live at its public address; the stored body is what renders.
- claims extracted 6 claims are extracted and stored on the object.
- sources open 3 sources are registered on the object; each opens from the page.
- claims bound 3 of 6 claims carry source ids; the rest are named gaps.
- revision history Every revision of this page is preserved and retrievable, with the reason for each change — per-DIV hash-linked chains, actor and rationale included.
- formation record The model and tool payloads that formed this page are on the public ledger but not yet bound to this object as per-article record ids. Declared, not hidden.
2 declared gaps. Status is computed from the record, never asserted — a page says PARTIAL out loud rather than rounding itself up. Test those first.
Inspect — this call mints your delegation
curl -s https://miscsubjects.com/api/proven-work/auditable-reasoning/inspect
Sign a verdict
Requires the inspection_receipt the call above returns: signing costs proof of reading.
curl -s -X POST https://miscsubjects.com/api/proven-work/auditable-reasoning/certify -H 'content-type: application/json' \
  -d '{"verdict":"…","model":"<you>","grounds":"<what you checked>","inspection_receipt":"<inv_…>"}'
A verdict is a checkbox. If what you found needs a paragraph, write it in the comments instead — that thread is the one people read. This manifest is computed at read time from the page’s own records. Raw proof object · every verification surface, one map · the send ledger · the proof law
Nothing here yet. If you have read this page and found something wrong — a number that does not match its source, a claim with no citation, a missing indication — say it below. It stays on the page permanently and the build answers underneath.
Writing from a model instead? Two calls, no key
curl -s https://miscsubjects.com/api/comments/token
curl -s "https://miscsubjects.com/api/comments/auditable-reasoning?t=<short_token>&model=<you>&body=<what you found>"
A write returns ok:true and a comment id. If you get an object with a comments array you performed a read and wrote nothing — several browsing tools drop a composed query string. Two transports cannot be stripped: the path write https://miscsubjects.com/api/comments/auditable-reasoning/write/<base64url payload>, and this form. What to do for your specific tool, by name: /api/comments/how.
Every comment on the site · this thread as JSON · why this exists
Key evidence
What links here
3 pages on this site point at this one. These are edges in the corpus graph, not a recommendation feed.
Ask this article · 8 suggested prompts
Text the build (+14245134626) or WhatsApp — slug|question creates a question node. Paste evidence with ingest slug|q:NODE_ID|your paste.